
Your own AI model, running wherever you want it
- We choose the model and approach that makes technical and economic sense for your task
- We fine-tune it on your data and shrink it so it fits the hardware you have or plan to buy
- We put it into production, connect it to your systems and keep watch on quality and cost
Sound familiar?
You do quality control by eye
You plan by guesswork, not by data
You retype invoices and forms by hand
You don't know which model and approach to choose
Your AI bill keeps growing and nobody can control it
Data must not leave, yet AI is exactly what you need
Why tackle your own model right now
A general model doesn't speak your language
Models have shrunk enough to fit at your place
The cost of entry has dropped
Prompting, RAG, fine-tuning, or custom training?
Prompting means setting instructions for a ready-made model without touching its weights – the cheapest step, sufficient for general tasks. RAG (retrieval-augmented generation) connects the model to your documents and databases so it answers from verified sources, but the model itself learns nothing. Fine-tuning adjusts an existing model on your data so it keeps your terminology, style and output formats. Custom training builds a model for a task language models cannot do – quality control from images, demand forecasting, form extraction.
The order is not accidental: each further step costs more and needs more data and more compute. That is why we start with the cheapest approach that solves the task and move to fine-tuning or custom training only when measurements on your data show it is needed. Hallucinations are not fixed by more training – RAG and testing take care of that, as we explain in the questions below.
That only settles what the model has to do. The second question, just as important for cost and for security, is where the model will run.
Cloud, your own server, or right next to the machine?
A cloud API is the fastest way to start. You buy no hardware, you pay for the volume of text processed and you get the strongest models on the market. But you pay for every query, your data leaves for the provider, and pricing and model availability can change without you. Your own server means a one-off investment and then only electricity, your data stays with you and the model does not change until you change it. Deployment right next to the equipment – in a workshop, in the field, on a technician laptop – works even without an internet connection.
To make a model fit your own hardware, it is usually quantized. In plain terms its internal numbers are stored at lower precision, so instead of sixteen bits per parameter it needs eight or four. A model with thirty billion parameters shrinks from sixty gigabytes to just under twenty and runs on a single graphics card. Quality drops a little – with four-bit quantization usually very little, at more aggressive levels noticeably. How much exactly it costs you on your task cannot be estimated, only measured.
Most companies end up combining both. Everyday traffic is handled by a local model whose cost and behaviour you know, and exceptionally demanding tasks reach into the cloud. We help set that boundary and wire it up so nobody has to police it by hand.
| Weight precision | A 30-billion-parameter model takes up | Effect on quality | When to use it |
|---|---|---|---|
| 16-bit, no quantization | about 60 GB | the reference point | When you have memory to spare and want maximum quality |
| 8-bit | about 30 GB | practically invisible | Server deployment where memory is still sufficient |
| 4-bit | 17 to 20 GB | small but measurable | The most common choice for a single graphics card |
| 2 to 3-bit | 10 to 13 GB | noticeable | Only when the model would not fit at all otherwise |
When a local model pays off and when it does not
It pays off
When query volume is steady and high. A cloud bill grows with every word processed, a server is bought once. For an agent running non-stop or batch document processing the investment returns within months.
When data must not leave the company. A local model is the simplest way to show a customer or an auditor where documents are processed.
When you need AI without an internet connection. A production line, the field, a closed network with no outbound access.
When you want certainty that the model will not change. Cloud models are updated and their outputs shift with them. A local model stays exactly as you approved it for production.
It does not pay off
When a handful of people use AI occasionally. At a few thousand queries a month the hardware takes years to pay back and the cloud is cheaper.
When the task is at the limit even for the best cloud models. On complex legal analysis or demanding programming a local model falls behind and there is no point hiding it.
When nobody is there to look after it. A server needs updates, backups and monitoring. Either we take that over, or somebody on your side has to own it.
What fits on which hardware
| Machine and memory | What actually runs on it | Response time | Power draw |
|---|---|---|---|
| Gaming graphics card, 24 GB | Extracting data from invoices and forms, sorting and summarising documents, searching company data. Not enough for an agent working on its own. | seconds to a minute | 225–300 W |
| Top gaming card, 32 GB | A company assistant over your documents, drafting customer replies, simpler agent steps under human supervision. | under a minute | 260–470 W |
| Professional card, 96 GB | Most office work at a quality close to mainstream cloud models, several users at once. | up to 5 minutes | approx. 350 W |
| Machine with unified memory, 96 GB | The same, but slower and on a tenth of the power. Suited to an agent running non-stop with nobody waiting for it. | up to 10 minutes | approx. 45 W |
| Compact AI workstation, 128 GB | The largest open models, batch processing overnight, testing before going live. | 10 to 30 minutes | approx. 75 W |
| Server GPU in a rack, 48 GB and up | Dozens of users at once, redundancy and administration like any other company server. | seconds, depending on load | depends on the build |
Work out the cloud against your own machine
An indicative calculation, not a quote. It sets the API bill against a one-off machine plus electricity and leaves out your own people time. Real numbers come from measuring your task.
Why tackle your own model with Mediatoring
Approach chosen by the task, not by fashion
We decide by what the task and your data actually need, and we tell you when your own model does not make sense. We recommend the cheaper route before you pay for the expensive one.
We measure before we deploy
Every model is compared with the baseline on a test set built from your real data. Public leaderboards are only a guide when choosing hardware; the binding number comes from your own tasks. So you know the accuracy before production, not after.
Ten years with AI, over twenty-five years with business data
We have worked with artificial intelligence since 2016 and with e-shops, ERP and websites for more than a quarter of a century. We know what company data looks like in practice, where to clean it and how to connect the model where it is actually used. We have the computing capacity, including access to the LUMI supercomputer.
Research, not just practice
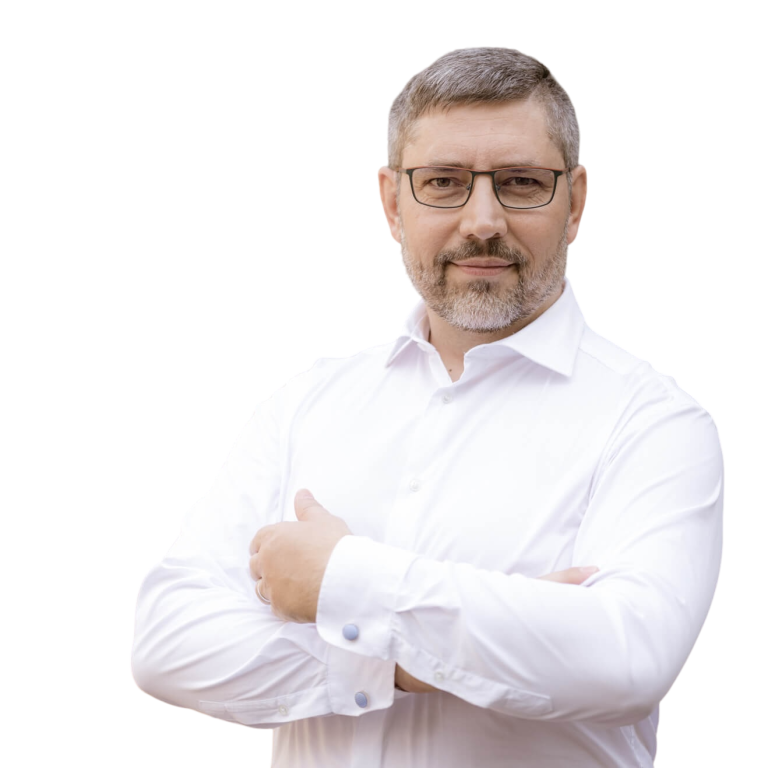
Founder Michal Kubíček researches at Silesian University how language models work with information about companies, and he is the author of books on SEO and optimisation for AI. He leads one of the largest Czech AI communities.
Who builds it
He has worked with artificial intelligence since 2016 and in online business for over twenty-five years. A doctoral student at Silesian University in Opava (brand representation in the outputs of language models), author of SEO books published by Computer Press and of books on optimisation for AI, columnist for Patriot magazine. He leads model training and fine-tuning personally with the Mediatoring team. He writes at kubicek.ai.
They trust us
Continental · Hyundai Motor · Groupon · Union of Towns and Municipalities of the Czech Republic · Technology Agency of the Czech Republic · Datasys · Spokar · Slovak Athletics Federation · Energy Centre of the Ústí Region · VŠÚO Holovousy
What we can build, fine-tune and deploy for you
| Type of service | What it includes | Benefit |
|---|---|---|
| Prompt tuning and RAG | Connecting a language model to company documents and databases without training | Accurate answers from your own data |
| Fine-tuning a language model | Tuning to your terminology, communication style and output formats | A model that writes and answers like your company |
| Computer vision | Image recognition: quality control in production, document extraction, object counting | Less manual work and fewer overlooked errors |
| Predictive models | Predicting demand, stock levels or breakdowns from historical company data | Planning by data instead of guesswork |
| Model selection and deployment | Comparing commercial, open and local models by cost and data requirements | A model that fits both the task and the budget |
| Training on the LUMI supercomputer | Custom training and more demanding fine-tuning where ordinary GPUs are not enough | Compute without investing in your own infrastructure |
| Model quantization and optimisation | Shrinking the model for your hardware and measuring how much quality changes | A model that fits and does not slow people down |
| Local model deployment | Inference server installation, API integration, access control and monitoring | AI in production without sending data out |
| Hardware and capacity design | Working out what machine the task needs and comparing it with cloud cost at the same volume | Buying by the numbers, not by the catalogue |
| Private RAG over company documents | Search and answers over your documents entirely inside your network | Answers from verified sources, nothing leaves |
| Local agent solutions | Agents working on their own over a model running on your infrastructure | Automation without monthly volume fees |
| Security and compliance evidence | Access control, query logging, documentation for GDPR and the AI Act | Evidence of who asked what and where data went |
| Measurement and cloud comparison | A test set from your data, measuring quality, speed and cost per thousand queries | Decisions based on numbers from your operation |
4 steps to your own AI model

Data and brief analysis

Model selection and approach

Training, fine-tuning and testing

Quantization, deployment and operation
How we work together
Intro call
Proposal and quote
First working version
Operation and growth
What it costs
Data and task assessment
Prompt tuning and RAG
Local model deployment
Custom model fine-tuning
Training and operation of your own model
Operation and monitoring
When a custom AI model pays off and where to run it
Frequently asked questions about AI model training and fine-tuning
How much does training or fine-tuning an AI model cost?
The price depends on the scope of the task, the size of the model and the amount of data we work with – fine-tuning a smaller model for a specific task costs something different from training a larger model on domain-specific data. During the initial consultation we go through your brief and prepare an indicative tailored quote, so you know what to expect before we start the project.
Which models and technologies do you work with?
We work with open language models (such as Llama or Mistral) as well as commercial APIs like GPT or Claude. Besides language models, we also train computer vision models and predictive models over business data. For more demanding training and fine-tuning we use the computing power of the LUMI supercomputer, one of the most powerful in Europe.
Who owns the trained model and the data we work with?
The model and all the data it is built on remain yours. We share nothing with third parties and never use it to train other projects – we work purely as a supplier on your infrastructure or in an environment we agree on in advance.
Can you connect the model to our ERP, accounting or e-shop?
Yes, integration with existing systems is a normal part of our projects – whether it is an ERP, accounting software, an e-commerce platform or internal databases. The model can then work directly with your real data and fit into the processes you already have in the company.
How does training or tuning a model work in practice?
First we clarify the goal together and go through the available data. Then comes data preparation and cleaning, the actual training or fine-tuning, testing on real scenarios and tuning based on the results. Finally we deploy the model and hand it over together with documentation on how to work with it.
Who benefits from investing in their own AI model?
A custom model makes sense for companies that work with specific or sensitive data, need to solve the same type of task repeatedly – such as quality control in production, document extraction or demand forecasting – or run into the limits of general tools like ChatGPT. If your task is more of a one-off or general nature, an off-the-shelf solution may be faster and cheaper – and we will tell you so honestly during the consultation.
How does communication work during the project?
We agree on regular consultations where we show interim results, discuss any changes to the brief and answer questions. If you prefer, we can also keep in touch continuously by e-mail or video call, whichever suits you.
Can the model be extended or retrained later?
Yes, there is no need to rebuild the model from scratch if your needs change or new data comes in. We can fine-tune it, extend it with new capabilities or retrain it on more recent data, so it grows with your company.
Who takes care of running, backing up and securing the model?
By agreement we can also run the model after deployment – including backups, monitoring and security measures. If you want to handle operation in-house, we hand over the model with documentation so you can manage it yourselves.
Why invest in your own model when ChatGPT exists?
ChatGPT is an excellent general assistant, but many business tasks are of a different kind: you won’t solve defect detection on a production line, demand forecasting or document extraction with it. And even for language tasks, a custom or fine-tuned model has advantages – it keeps to your terminology and style, runs on infrastructure under your control, and at high query volumes works out cheaper than a paid API.
How do you protect data and privacy during training?
Data protection is essential for us – we work only with data you are authorised to use, and we set up the project so that sensitive data never leaves your infrastructure or the agreed secure environment. We comply with the GDPR, sign a non-disclosure agreement (NDA) with all parties, and never use your data to train other models or projects.
Can you improve or fine-tune a model we already use?
Yes, you don’t have to start from scratch. If you already work with a model and are not happy with the results, we look at exactly where it falls short and propose whether fine-tuning, adjusting prompts and data, or switching to a different model is the more effective route.
What will you need from us at the start of the project?
What helps most is an idea of the problem you want to solve and access to the relevant data – the documents, databases or systems the model is supposed to work with. We take care of the rest, including the technical setup.
How do I arrange a free consultation?
Just write to us via the contact form on this page, call +420 555 333 158, or simply pick a slot for a 15-minute call in the calendar. We get back to you within one working day and on the intro call we discuss your brief, your data and the possible solutions. Neither the consultation nor the proposal costs anything or commits you to anything.
Will training a model stop the AI from making things up?
Additional training alone won’t; hallucinations are inherent to language models. Reliability is handled differently: by connecting the model to your documents and databases (RAG) so it answers from verified sources, and by thorough testing on real examples. Fine-tuning adds the right terminology and form of answers on top. We combine both according to what the task requires.
Do you also do image recognition and predictions, not just chatbots?
Yes. Language models are only part of our work. We also train computer vision models for quality control or reading documents, and predictive models for planning demand, stock and maintenance.
What hardware do we need for our own AI model?
It depends on the size of the model and how many people will use it. For document data extraction and text classification a single powerful graphics card with 24 GB of memory is enough. For a company assistant over your documents a 32 GB card is a sensible start, and for several users at once 96 GB and up pays off. We never give the recommendation straight from a table though – we measure the model on your data first and propose the setup that genuinely covers the task.
How much will we save compared with paying for a cloud API?
The cloud is billed by the volume of text processed, so cost grows as AI settles into the company. Your own server is bought once and then costs electricity and administration. The turning point usually sits where the monthly API spend would cover the hardware payment, which for an agent running non-stop is a matter of months, while for occasional use it never arrives. The calculator on this page gives you the rough figure; the exact one comes from your real query volume.
Is a local model worse than ChatGPT or Claude?
On the most demanding tasks yes, and there is no point hiding it. The gap is far smaller than it used to be, and for everyday company work – data extraction, summarising, answering over your own data, classification – a well-deployed local model is fully usable today. What decides is not a leaderboard but whether it handles your specific task, which is why we measure it before deployment.
What is quantization and how much does it degrade the result?
Quantization shrinks a model by storing its internal numbers at lower precision. A model with thirty billion parameters takes about sixty gigabytes at full precision and just under twenty at four-bit, so it fits on a single graphics card. The quality loss at four bits is usually small and at more aggressive levels noticeable. The exact figure for your task cannot be estimated, only measured on a test set, and that is part of our work.
Can we run the model on a server we already have?
Often yes, especially if it holds a graphics card with enough memory. We audit what you have, measure what will actually run on it and how fast, and only then say whether adding memory, swapping the card or buying a new machine is the answer. Sometimes topping up the existing server works out cheaper than a new one.
Can you deploy AI where there is no internet connection?
Yes. Once installed, a local model needs no outbound connection, which suits production floors, closed networks and field work. What remains is updates and backups, usually handled in a service window or on removable media according to your security rules.
How often does a local model get updated and who does it?
A local model does not change by itself, which is its advantage – what you tested is what runs. New model versions appear continuously and moving to a newer one only makes sense when it measurably helps on your tasks. If you have operation and monitoring with us, we watch that for you and propose the move with numbers in hand.
How does local deployment help with GDPR and the AI Act?
Mainly it simplifies evidence. When processing happens on your server, there is no transfer of personal data to a third party and no question about where data is stored or for how long. The remaining obligations do not disappear, which is why deployment comes with access control, query logging and a description of how the system works, so there is something to build an audit on.
Can we run AI agents on top of a local model?
Yes, and it is one of the main reasons to go local. An agent running non-stop and processing every incoming e-mail or document consumes large volumes in the cloud and its bill is hard to predict. On your own model it runs for the price of electricity. Designing and building agents is covered by our AI agents and workflow service.
What if the local model stops being good enough?
We build the solution so the model can be swapped without rebuilding everything around it. The interface your systems call stays the same, so you can deploy a larger model, move to stronger hardware, or route demanding queries to the cloud and keep the rest local. That combination is what most companies with a well-built setup end up using.